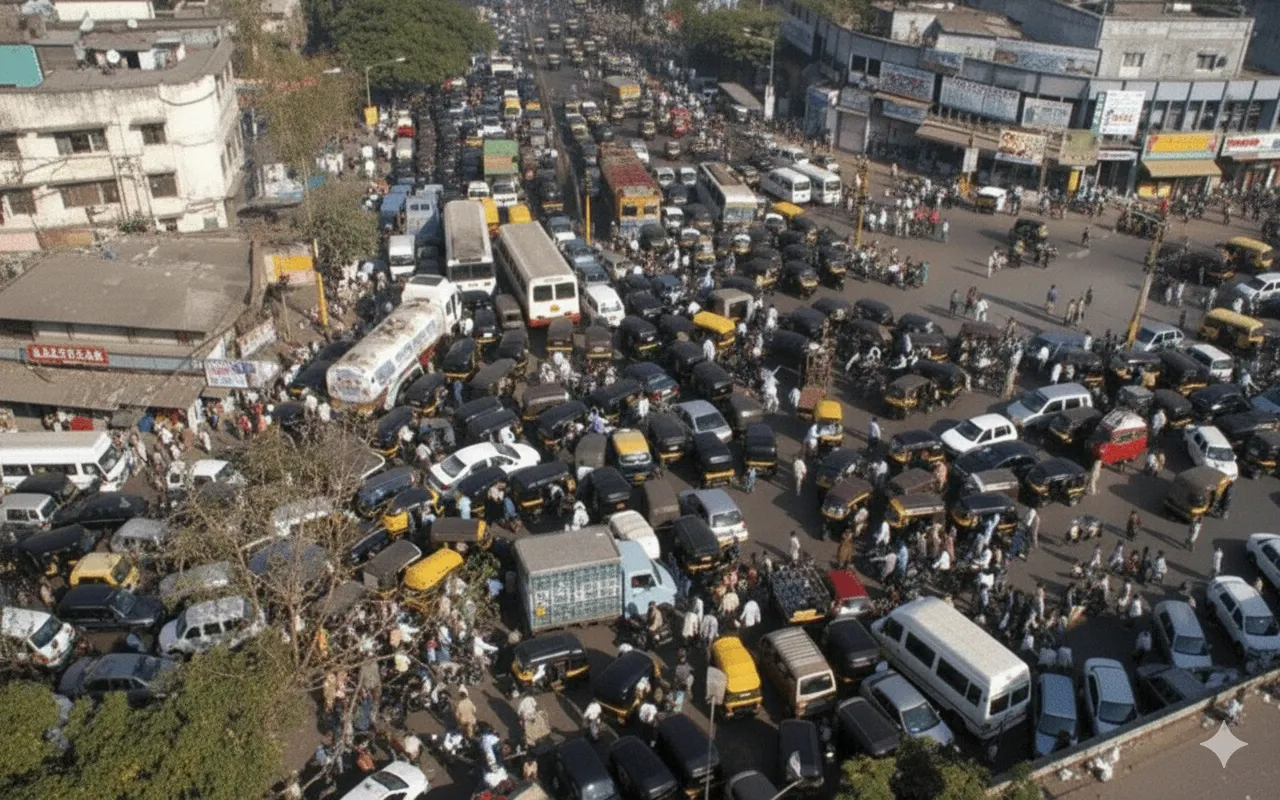# Siddhartha Varma
> Software engineer. Personal site with blog posts and work history.
Siddhartha (Sid) Varma is a software engineer with experience at Zomato, Groww, and various startups. Backend first, product minded. Currently exploring AI-native tooling and Machine Learning.
## Links
- [GitHub](https://github.com/BRO3886)
- [LinkedIn](https://linkedin.com/in/siddharthav22/)
- [Twitter](https://twitter.com/sidv_22)
- [Email](mailto:siddverma1999@gmail.com)
- [Telegram](https://t.me/vaerma)
## Work Experience
### Feeble
Apr 2025 - Present | [Feeble](https://feeble.io/)
**Senior Software Engineer** (Jul 2025 - Present)
AI-powered task management, Slack bots with Temporal workflows, and a Calendly alternative with multi-tenant scheduling.
**Freelance Consultant** (Apr 2025 - Jun 2025)
Podcast studio management UI in Next.js and automated thumbnail generation via Supabase functions.
### Flexprice
Feb 2025 - July 2025 | [Flexprice](https://flexprice.io)
Error handling redesign in Go, PDF invoice generation with Typst, calendar billing, Stripe sync workflows, and an MCP server for AI agent integrations.
**Freelance Consultant** (Feb 2025 - July 2025)
### Zomato
Jul 2022 - Dec 2024 | [Zomato](https://zomato.com)
**Software Engineer II** (Jul 2024 - Dec 2024)
Led homepage features and autosuggest improvements using Redis, Kafka, and DynamoDB. Built partnerships integration serving 2500+ corporate employees.
**Software Engineer I** (Jul 2022 - Jun 2024)
Search re-ranking and distributed catalog search indexing 100M+ SKUs on Solr.
### Groww
Jan 2022 - Jun 2022 | [Groww](https://groww.in)
Core platform services, Help & Support microservice redesign, and event ingestion with Kafka and Go.
**Software Engineering Intern** (Jan 2022 - Jun 2022)
### Nearcast
Apr 2021 - Aug 2021 | [Nearcast](https://nearcast.com)
Flutter app development with native modules for video capture and processing.
**Flutter Developer** (Apr 2021 - Aug 2021)
### Winuall
Jan 2021 - Apr 2021 | [Winuall](https://winuall.com)
Marketplace backend, Jitsi integration, and deployment automation.
**Backend Dev Intern** (Jan 2021 - Apr 2021)
### Nirmitee.io
Sep 2020 - Nov 2020 | [Nirmitee.io](https://www.nirmitee.io/)
Built the Byteseal mobile app for this Pune-based product studio.
**Flutter Intern** (Sep 2020 - Nov 2020)
### OYO Rooms
Jun 2019 - Jul 2019 | [OYO Rooms](https://www.oyorooms.com/)
Internal tech support portal with Django and Freshdesk API integration.
**Intern - Technology** (Jun 2019 - Jul 2019)
## Projects
### gtasks
A full-featured CLI client for Google Tasks. Manage task lists, create and complete tasks, all from the terminal.
- URL: https://github.com/BRO3886/gtasks
- Tech: Go, Google API, CLI
- Stars: 126
### mcp-memory-custom
An MCP server that gives AI agents persistent memory with configurable storage locations. Works with Claude and other MCP-compatible clients.
- URL: https://github.com/BRO3886/mcp-memory-custom
- Tech: JavaScript, MCP, AI Tooling
### QwikScan
Document scanner app built with Flutter and BLoC. Won first place at Apptitude 2020 hackathon by ACM VIT.
- URL: https://github.com/BRO3886/qwikscan
- Tech: Dart, Flutter, BLoC
- Highlight: Hackathon Winner
### genlookup
Chrome extension for instant LLM-powered explanations. Select any text, right-click, and get a contextual breakdown.
- URL: https://github.com/BRO3886/genlookup
- Tech: JavaScript, Chrome Extension, LLM
### portfolio-v2
This site. Static Astro build with dual-theme system, editorial blog layout, and Cloudflare edge deployment.
- URL: https://github.com/BRO3886/portfolio-v2
- Tech: Astro, TypeScript, Cloudflare
## Blog Posts
### Software Engineering In The Agentic Era
- URL: https://sidv.dev/blog/software-engineering-agentic-era/
- Date: 2025-09-21
- Author: Siddhartha Varma
- Tags: ai, software engineering, opinion
# When Prompting Becomes Programming
Prompt in, app out. The code fails, but too many builders cannot tell you why.
My feed is full of "vibe coders" shipping apps with prompts, accepting whatever the AI generates without understanding it. People who once struggled with basic CSS now call themselves "AI engineers".
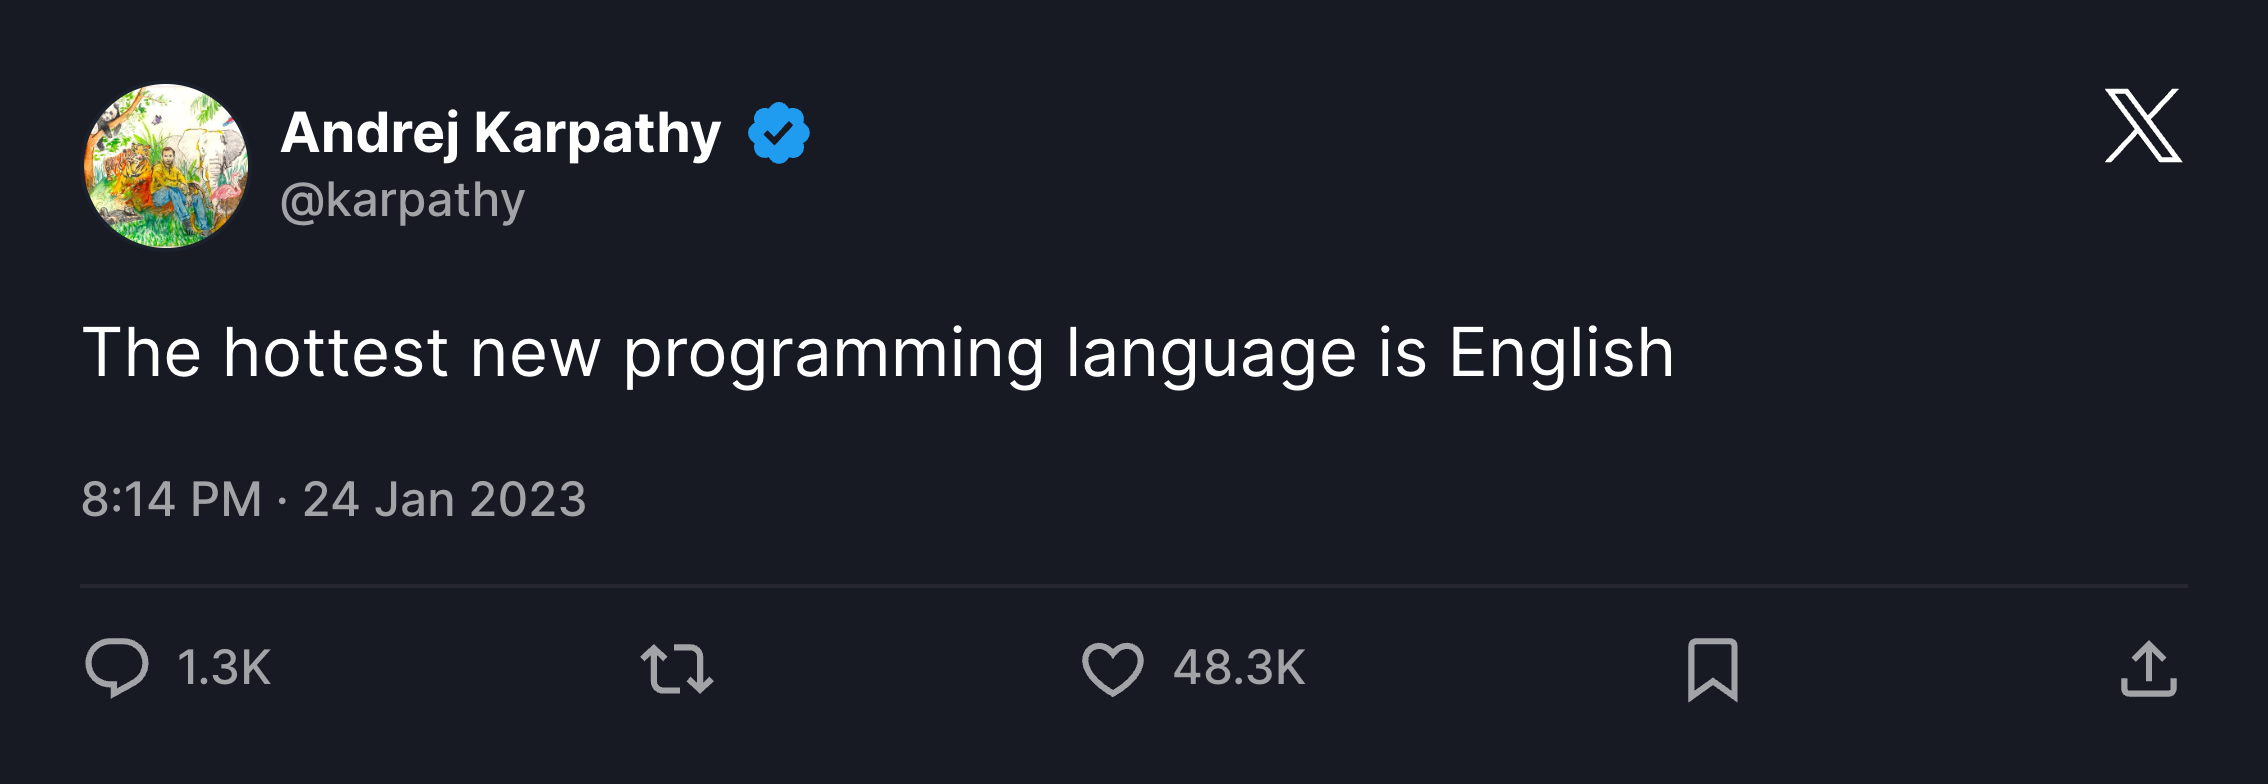
In two years, we've jumped from awkward tab completions from Copilot to it raising PRs directly on GitHub. This feels like developers' Excel moment: coding agents remove the tedium of typing, but fundamentals still matter, just like we still teach math without calculators.
Andrej Karpathy's very popular tweet
We've had many shifts — from punch cards to high-level languages — but this one changes the relationship, not just the medium. More and more, prompting is treated as programming. That's the difference, and it's why I'm concerned about where we're headed.
## Tesla vs Mumbai Traffic
A good chunk of people believe AI agents like Claude Code, Codex, and Copilot are like Tesla Autopilot — smooth and predictable, hands-off coding. You just prompt and magic happens.
On the other hand, my experience has been more like navigating rush hour traffic in Mumbai. It's so chaotic. A Tesla would just give up, and you, a driver well-versed with Mumbai traffic, would want to grab the wheel to avoid crashing into someone.
a chaotic congestion in Mumbai, modified with nano 🍌
Vibe coders just prompt their way through their problems, riding on AI confidence and ✨ vibes ✨. They feel fast, they look productive, they feel productive.
But I have seen their code, it is unmaintainable garbage.
## Garbage In, Garbage Stays
I've been writing code for a while now, and I have seen good code countless times. Human written code isn't perfect. Sometimes the variable names are cryptic, sometimes there are bugs. But there is surgical precision there. Every line has a reason. When humans write code, less is more. Less code means fewer bugs. Less code is more performant.
LLMs are like the friend who never shuts up. Claude gives you 50 lines when 5 would do. It over-engineers solutions and adds backward compatibility for features you have not even released. It will create 5 utility functions doing the same thing in different files. It creates abstractions that sometimes make no sense at all. I recently worked on a codebase where the AI had imported two different google libraries just to fetch some calendar data.
The thing that worries me most is garbage code has a persistence problem. Unlike regular refactoring where you gradually improve a system, AI-generated bloat tends to compound. Before you know it, the codebase has become a nested mess of dependencies and abstractions that nobody fully understands.
Sure you can rewrite garbage code, but it requires recognizing it as garbage first. If you do not understand a domain/library/framework well enough to spot the BS, you are stuck maintaining an increasingly complex system that becomes increasingly harder to debug with each iteration.
## The Fake Dopamine of Speed
The other thing that has been a bother is a fake dopamine rush from vibe coding. You start to feel like speed is your friend. You prompt something and it works. Instant gratification.
I don't think this speed is real. Yes, speed matters when you're building software in a highly competitive and ever-changing landscape, but at what cost?
When you're moving fast, prompting your way through the problems, you're not actually understanding what you're building. You're not learning the patterns. You don't form mental models. You're not developing the intuition to understand where things might break, and they will, and when they do, you're stuck — **because you can't debug what you don't understand**.
bob the confused builder
That fake speed you get from vibe coding? It disappears the moment something goes wrong. Suddenly you're slower than everyone else because you have to reverse figure out what's happening. I've faced this too. I spent a day debugging Claude generated cross-timezone slot booking flow with google calendar conflict mitigation, finally gave up and started handrolling the implementation.
Teams move lightning fast in the beginning, then hit a wall when they need to maintain or extend what they built. The technical debt compounds. The bugs multiply. And all that speed you thought you had? It vanishes.
This speed trap is particularly seductive because it feels so different from traditional development bottlenecks. But recognizing it is crucial for using AI tools effectively.
## Where AI Actually Shines
Don't get me wrong: I'm not anti-AI. These tools are genuinely powerful when used properly. I've found AI incredibly helpful for specific tasks: generating test cases, writing boilerplate code, explaining unfamiliar APIs, and handling tedious migrations. Claude is excellent at walking through complex codebases and explaining implementation. I recently used it to handle a complex merge conflict as well!
The difference is in how you use them. For example, instead of asking it to "create X", I spend time with it understanding the existing codebase, often creating markdown documents for things that are important. In this process, I build a mental model, I understand the context. Then I ask Claude to implement the task specifically how I want. I use the documents to steer it, I ask it to write code like I want. I control the architecture. I know what good output looks like. I can spot when something's wrong. The AI is amplifying my existing knowledge, not replacing it.
This is the crucial distinction that vibe coders miss. They're trying to use AI as a replacement for understanding rather than as an accelerator for understanding. That's where the problems start.
So what does responsible AI-assisted development actually look like in practice?
## What I Think We Should Be Doing
I've been using AI as a learning accelerator rather than a replacement for thinking. As I suggested with the last example, the key is maintaining agency over the process while leveraging AI's strengths. I keep drilling down until I understand the fundamentals. The AI can follow my curiosity as far as the context window allows, and it'll find creative ways to explain concepts that would take me hours to research manually.
When I'm using Claude Code for development, I've developed a process that keeps me in control:
- **Plan what you want first** — don't just throw problems at the AI
- **Read Claude's plan before accepting anything** — prompt it to tell what exactly it is going to change and where
- **Question every decision** — just because it sounds smart doesn't mean it is
- **Research the concepts I don't understand**
- **Rarely auto-accept changes**
I've also been trying to solve problems from first principles more often. When I land on something I don't know how to implement, I use Claude as a brainstorming partner, not the author.
## Why I Think This Moment Matters
Here's what I've noticed: everyone's struggling with this transition. Senior engineers who spent decades building mental models are watching them get disrupted. Junior developers are questioning whether they should even learn fundamentals. Mid-level engineers are wondering if their experience still matters.
But I think this disruption creates opportunity for anyone willing to adapt. We can learn to see AI tools for what they really are — powerful but (currently) dumb assistants that need supervision. We can develop the skills to prompt effectively while understanding the fundamentals deeply enough to know when the AI is leading us astray. I've seen this work out very well for engineers with experience and early adoption of AI tools.
The companies that figure this out first are going to dominate. They need engineers who can move fast with AI without sacrificing quality, engineers who can debug AI-generated code and engineers who have enough context to make correct architectural decisions.
While everyone's panicking about AI replacing jobs, I think they're missing the biggest opportunity in first principles thinking. This agentic era actually creates more room for this approach because you're not constrained by "this is how it has always been done".
## Bottom Line
I don't think developer jobs are disappearing. I think they're evolving into something more important. We're not just writing code anymore. We're steering intelligent systems, maintaining quality, and making sure the software that gets built is actually worth building.
The vibe coders will flame out when their lack of fundamentals catches up to them. The booking flows with race conditions? The bloated abstractions? The security vulnerabilities hidden in AI-generated code? They'll all surface eventually, and someone will have to clean up the mess.
The engineers who take this opportunity to deeply understand both AI capabilities and software fundamentals will be invaluable. They'll be the ones who can move fast without breaking things. Who can debug the un-debuggable. Who can make the hard architectural decisions that determine whether a system scales or not.
This isn't about replacing developers. It's about separating the engineers who understand what they're building from the ones who were just going through the motions.
The Agentic Era doesn't scare me. It excites me, because I think it's going to make the difference between good and great engineers more obvious than ever.
The question isn't whether AI will change how we build software — it already has. The question is whether you'll use it as a crutch or as a catalyst for becoming a better engineer.
Humans set the blueprint. AI follows it.
---
_This article is also AI-assisted, but as always, the thoughts, ideas and examples are original._
---
### Green Tea GC: How Go Stopped Wasting 35% of Your CPU Cycles
- URL: https://sidv.dev/blog/green-tea-gc-how-go-cut-memory-waste/
- Date: 2025-07-13
- Author: Siddhartha Varma
- Tags: go, garbage collection, performance
## Introduction
Your Go application is performing well, handling requests efficiently. But there's a performance issue you might not be aware of— the garbage collector **is wasting 35% of CPU cycles waiting for memory access**. Every time the GC jumps between objects scattered across RAM, your CPU sits idle while data is retrieved from memory.
Green Tea GC, Go's experimental new garbage collector reduces this waste by upto 50%. The garbage collector is available as an experiment in the upcoming Go 1.25, expected to be released in [August 2025](https://tip.golang.org/doc/go1.25).
## Revisiting Garbage Collection
Before we dive into how Green Tea works, here's a quick refresher on Garbage Collectors:
Any program typically allocates objects on two types of memories, Stack and Heap. Stack memory is generally easy to manage and clean (references are dropped along with frames after the work is done), while some other objects like constants live on the Heap.
In the early days of programming, programmers used to manage memory on their own (remember malloc from C?). This meant that if the memory wasn't freed after use, it lead to memory leaks and if you freed twice, a crash.
Then came Garbage Collectors, popularized by languages like Java, JS (V8). The idea was novel, instead of allocating and deallocating by hand, the runtime would manage the memory instead.
Garbage Collection visualized by ChatGPT
> The compiler can also figure out which objects go to the heap, which objects stay on the stack. This is called [Escape Analysis](https://en.wikipedia.org/wiki/Escape_analysis).
### Stop The World
Early Garbage Collection algorithms were quite naive like "Stop The World". STW completely halts the execution of the program to run a collection cycle. This guarantees that new objects are not allocated or the references are not changed when the collector is running.
But this meant that the program pauses for long duration, sometimes even for seconds(!) when the GC is running. This was a cause for concern in high availability applications like web servers.
### Concurrent Garbage Collection
Concurrent Garbage Collectors allow for garbage collection to occur at the same time when the application is running, minimizing pauses and improving performance, especially in real-time systems. They are designed to reduce "stop-the-world" pauses, where the application is halted entirely for garbage collection.
But these have a higher CPU overhead and implementation complexity — if this runs for a longer duration one cannot guarantee prohibition of new object allocations or reference changes.
## Go's Garbage Collector
Go's Garbage Collector has gone through various transitions, starting from a simple STW mark-sweep to what we have now: **A concurrent, Tri-Colour Mark and Sweep Garbage Collector**.
### How does the current GC work
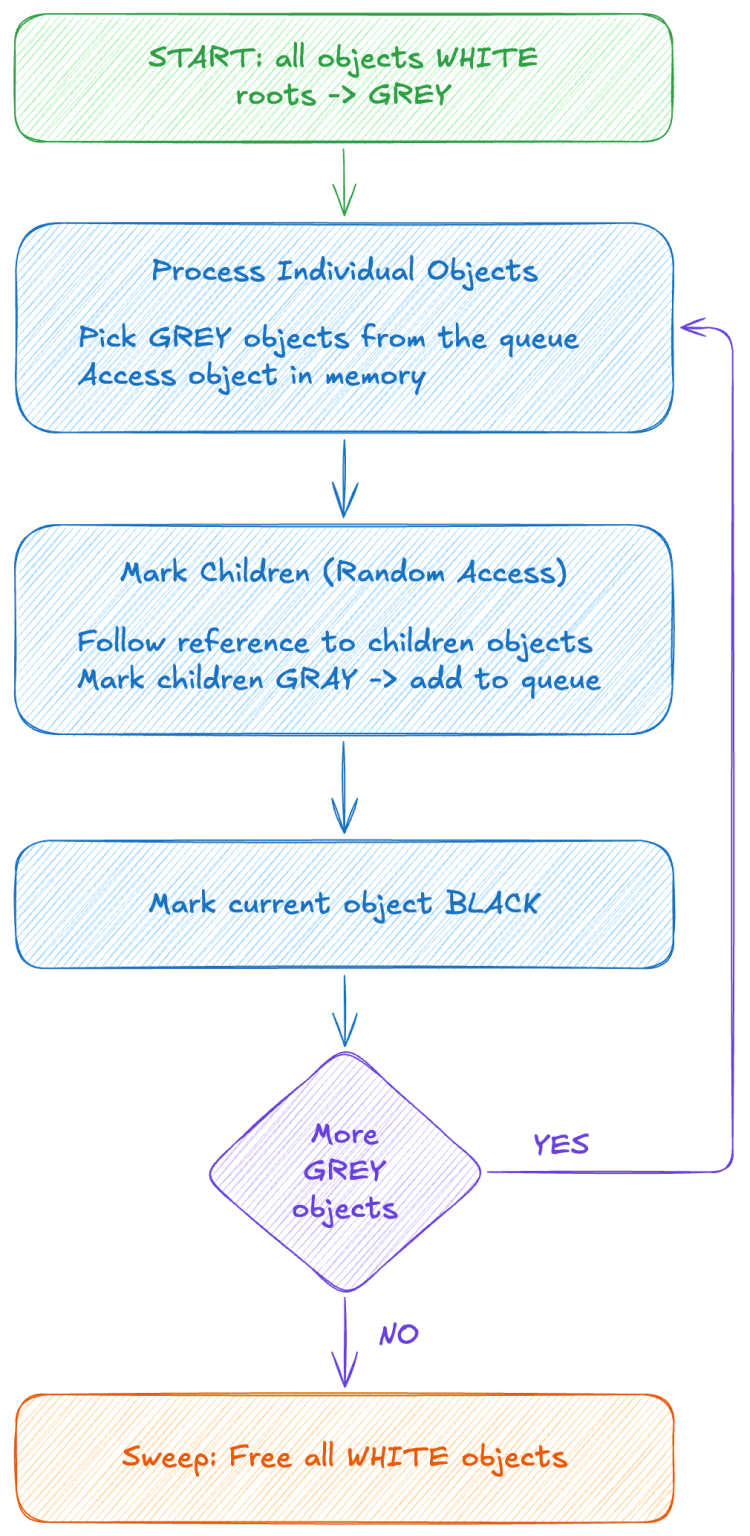
The current GC runs in two phases — Mark and Sweep. In the Mark phase, we assume all objects to be *white* (unreachable). We start at the root objects (constants etc), mark them as *grey.* All grey objects are added to a queue to be processed. We pick a grey object from the queue and start processing it's children. As soon as a child is marked grey, it's added to the queue and the parent is marked *black.* At the end, we have a mix of black and grey *accessible* objects. In the Sweep phase, we find all the *inaccessible* white objects (garbage) and clean it.
Tri-Colour Mark and Sweep
This algorithm is brilliant because it can run while your program continues executing. Go adopted this approach and refined it into one of the best garbage collectors in the industry, with pause times under a few milliseconds. But there is still a problem lurking beneath the surface.
### Performance Bottlenecks in current GC
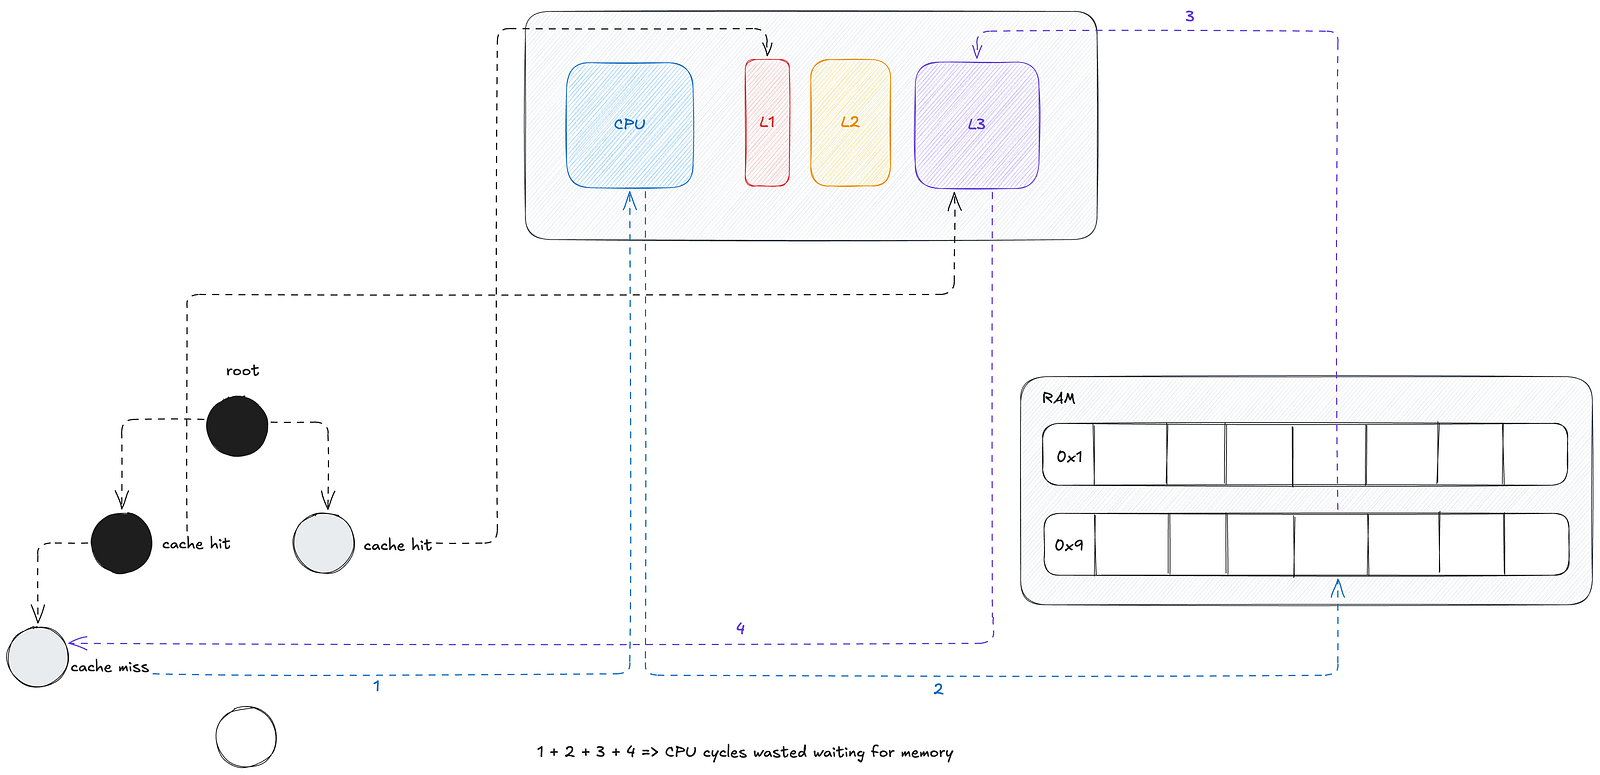
Modern CPUs process instructions at gigahertz speeds, but accessing main memory (DRAM) requires 200–400 CPU cycles compared to just 1 cycle for L1 cache access. To bridge this performance gap, CPUs use a hierarchy of caches (L1, L2, L3) — each level larger but slower than the previous.
The current garbage collector creates poor **spatial locality** by following object references randomly across memory. When the GC jumps from object A (at memory address 0x1000) to object B (at 0x5000), it likely causes a cache miss. The CPU must then wait hundreds of cycles to fetch the new data from DRAM.
Cache misses causes wastage of CPU cycles
This memory access pattern is where Go's current GC becomes a performance bottleneck. Studies show that **approximately 35% of GC CPU cycles are spent stalled on memory accesses**, excluding knock-on effects.
## Green Tea Garbage Collector
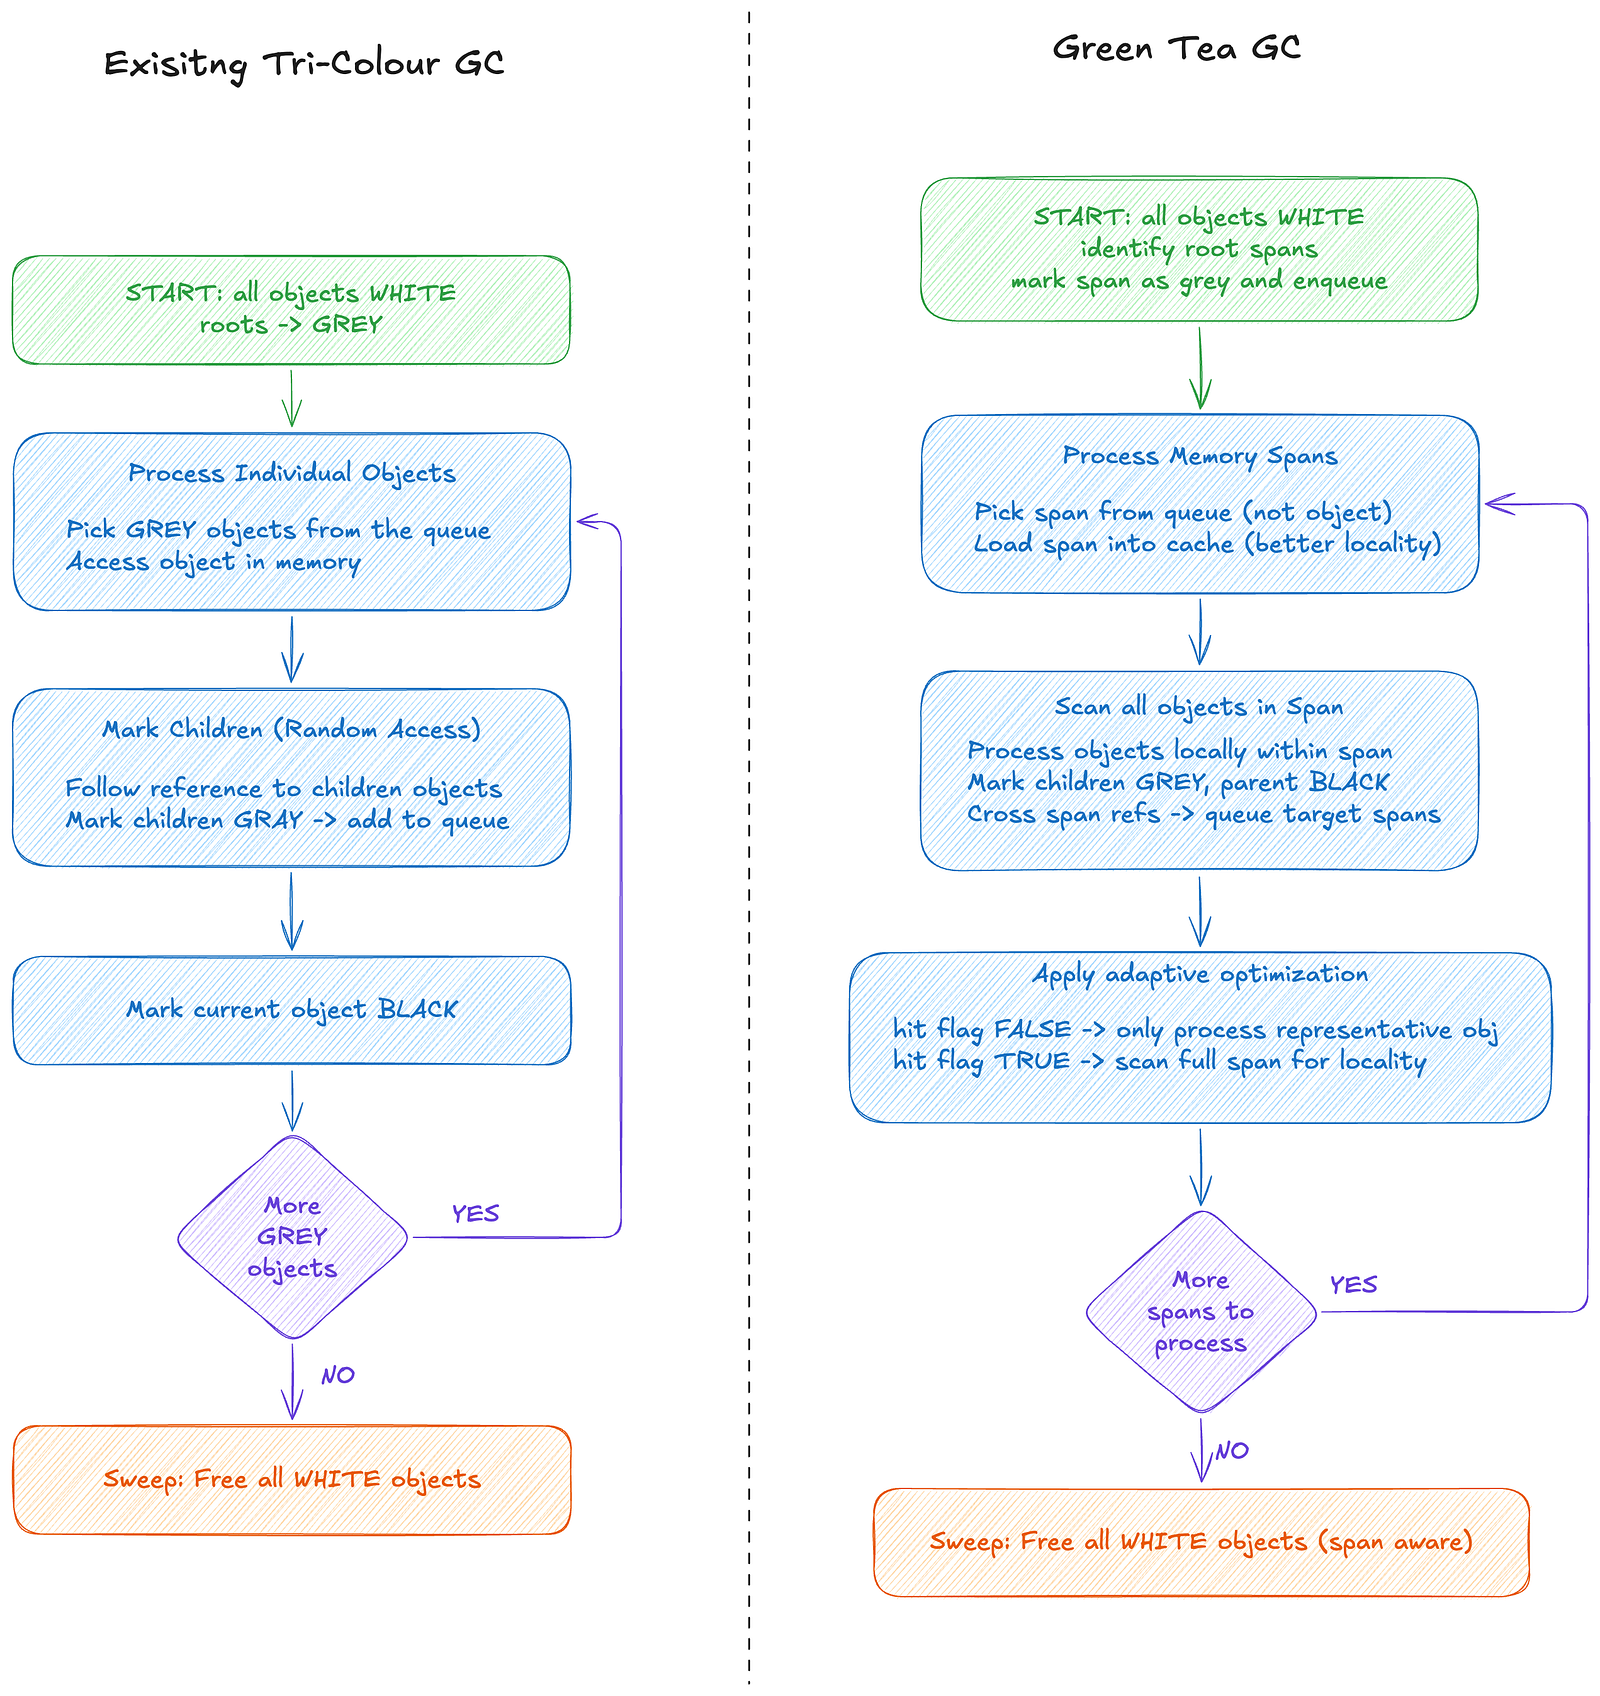
Enter Green Tea. Instead of frantically jumping between objects and causing cache misses left and right, Green Tea groups memory into blocks called **spans**. It processes entire spans together. By this method, on a cache miss, you load the entire span into the cache. This reduces the CPU cycle wastage and improves the GC performance.
But that's not all. What if the span has only one marked object? Processing the entire span would be inefficient. The algorithm takes this into account and behaves in an adaptive manner. Green Tea solves this with **representative object** optimization.
It tracks the object which caused the span to be queued and uses a *hit flag* to detect if more objects get marked while the span is waiting. If more objects get marked, the hit flag is true and we process the entire span for *maximum locality.* If the hit flag is false, just process the representative object.
Existing GC vs Green Tea
## Results
The results speak for themselves. In GC-heavy benchmarks, Green Tea shows 10 to 50% reduction in garbage collection CPU cost. On multi-core systems, the benefits are even greater. Green Tea includes work-stealing mechanisms similar to Go's scheduler, and there are even prototype SIMD-accelerated scanning kernels showing additional improvements.
Green Tea is available as an experimental feature in Go 1.25. Enable it with the following flag when building, after downloading Go 1.25.
```
$ GOEXPERIMENT=greenteagc go build
```
### References
- Green Tea Discussion — [https://github.com/golang/go/issues/73581](https://github.com/golang/go/issues/73581)
- Tracing GC — [https://en.wikipedia.org/wiki/Tracing_garbage_collection](https://en.wikipedia.org/wiki/Tracing_garbage_collection)
- Getting to Go: The Journey of Go's Garbage Collector — [https://go.dev/blog/ismmkeynote](https://go.dev/blog/ismmkeynote)
- Go GC: Prioritizing low latency and simplicity — [https://go.dev/blog/go15gc](https://go.dev/blog/go15gc)
---
### A Deep Dive into Dynamo's Architecture and Scale
- URL: https://sidv.dev/blog/dynamodb-architecture/
- Date: 2025-01-31
- Author: Siddhartha Varma
- Tags: dynamodb, aws, system design, databases

## Intro
On Prime Day 2021, Amazon's systems made trillions of API calls to DynamoDB, peaking at 89.2M requests per second (RPS), all while maintaining single digit millisecond latency. Yet, many developers struggle with database scaling issues that DynamoDB was created to solve.
Having worked extensively with DynamoDB at [Zomato](https://peerlist.io/company/zomato), I have also hit the same roadblocks, like hot partitions throttling applications, costs spiraling due to over-provisioning and data models that worked perfectly in other databases suddenly becoming performance bottlenecks. These challenges often stem from approaching DynamoDB with a traditional database mindset.
In this article, I'll dive into DynamoDB's architecture through a system design perspective. We'll explore the fundamentals of dynamo, how it's scaling and performance management differs from traditional databases, and more importantly - how to architect your applications to harness the full power of dynamo. Whether you're debugging performance issues, optimizing costs, or just starting with DynamoDB, understanding these internals will help you make better design decisions.
## Understanding DynamoDB's core principles
At the heart of DynamoDB's robustness and scalability lie six core principles around which it was architected. These principles prioritize simplicity, predictability, and reliability. Let's explore each, starting with perhaps the most counterintuitive:
### 1. Predictability over peak performance
This sounds very counterintuitive from a software perspective. Shouldn't one chase maximum throughput? While other databases also follow this approach, DynamoDB takes a contrarian stance - predictable performance matters more than peak performance.
If you marinate on this, it does make a lot of sense from a database perspective. What good is a lightning fast database which occasionally hangs for several seconds - even milliseconds? The latency spikes will ultimately affect application performance. DynamoDB's architects recognized this early on and set an ambitious goal - complete all requests with sub 10ms latencies.
How does it achieve this? Through some clever architectural decisions:
- **Global Admission Control** to manage capacity across entire tables, preventing any single partitioning from becoming a bottleneck
- Automatic partitioning to distribute I/O load evenly, even as access patterns change
- Proactive monitoring and rebalancing to prevent resource exhaustion before it impacts performance
- Multi-tenant architecture with strict resource isolation ensures consistent performance even under varied workloads
The result - Once *properly* configured, applications can rely on consistent performance whether they're handling normal traffic or sudden spikes. No more over-provisioning "just in case" or late-night panic when traffic patterns change.
### 2. Multi-tenant Architecture with Isolation
Unlike traditional databases where you might have dedicated instances, DynamoDB takes a different approach - it runs multiple customer's workloads on the same physical machines.
Now, you might be thinking, does it not introduce the [noisy neighbour problem](https://docs.aws.amazon.com/wellarchitected/latest/saas-lens/noisy-neighbor.html)? This is where DynamoDB's clever resource management comes in:
- Resource Reservation - Each table gets guaranteed capacity through token bucket allocation. When you provision throughput or use on-demand tables, DynamoDB reserves corresponding resources, ensuring your workload gets its fair share regardless of other tenants
- Strict Workload Isolation - Storage nodes host replicas from different tables and customers, but use partition-level token buckets to enforce throughput limits. Even if one tenant's workload spikes, it can't consume more than its allocated capacity, protecting other tenants' performance.
- Dynamic Load Balancing - DynamoDB's autoadmin service continuously monitors storage node utilization. If a node's throughput exceeds a threshold percentage of its maximum capacity, DynamoDB automatically redistributes partitions to maintain balanced load across the fleet.
- Proactive Capacity Management - Rather than waiting for resource exhaustion, DynamoDB tracks consumed capacity trends and automatically rebalances partitions before performance is impacted. Storage nodes independently report when they're approaching capacity limits.
These mechanisms ensure workload isolation between co-resident tables while maintaining high resource utilization. The benefit of this is cost savings, which gets passed down to customers while giving performance guarantees.
Multi-tenancy in DynamoDB
> [Autoadmin service](https://arc.net/l/quote/dftpozfb) is responsible for fleet health, partition health, scaling of tables, and execution of all control plane requests.
### 3. Boundless Scale for Tables
DynamoDB takes another contrarian approach with this principle. In traditional databases, we often have to carefully plan capacity and manage storage thresholds. Unlike these databases - for DynamoDB there are no predefined limits for the amount of data each table can store. Tables grow elastically to meet the demand of the customers' applications.
DynamoDB is designed to scale the resources dedicated to a table from several servers to many thousands as needed. How does DynamoDB achieve this seemingly infinite scalability? The secret lies in its partitioning strategy.
When you create a table, DynamoDB splits it into multiple partitions. Each partition being a dedicated slice of storage and compute that's responsible for a specific range of keys. These ranges are organized so that no two partitions overlap (disjoint ranges), and each partition handles all keys within its assigned range (continuous ranges).
For example, if your table uses numeric keys from 1-100, you might have:
- Partition A: Keys 1-35
- Partition B: Keys 36-70
- Partition C: Keys 71-100
Each key range is handled by exactly one partition, with no gaps or overlaps between partitions. As your table grows in size or throughput demands increase, DynamoDB automatically splits these partitions when:
- **Data Size**: When a partition's stored data exceeds its size threshold. This ensures no single partition grows too large to manage.
- **Throughput**: When a partition's consumed capacity consistently exceeds partition limits. DynamoDB monitors actual usage patterns and splits partitions based on observed traffic, not just size.
This automatic splitting enables tables to scale horizontally as they grow. Each new partition adds more dedicated storage and compute capacity to your table, all managed transparently by DynamoDB.
Automatic splitting
### 4. High Availability
In today's world, even a few minutes of database downtime can severely impact businesses. DynamoDB is architected for high availability, offering a 99.99% SLA for regular tables and an even higher 99.999% SLA for global tables.
At its core, DynamoDB achieves this through a sophisticated replication strategy. Every partition of your table is replicated across multiple Availability Zones (AZs) - physically separate data centers in the same region. But replication alone isn't enough - it's how DynamoDB manages these replicas that makes the difference.
Each partition has multiple replicas distributed across different AZs, forming what's called a **replication group**. Within each group, one replica acts as the leader, coordinating writes and strongly consistent reads.
Interaction Between Core Components
Here's how it works:
**For writes**
- When a write request arrives, the leader generates a WAL (write ahead log) record
- This record must be persisted by a quorum of replicas before acknowledging the write
- Even if one replica fails, as long as the quorum exists, writes continue uninterrupted
**For reads**
- Strongly consistent reads are served by the leader
- Eventually consistent reads can be served by any replica
- This flexibility allows it to balance load and maintain availability even during failures
In case when things go wrong, DynamoDB has multiple layers of failure protection:
- **Fast recovery** - If a replica becomes unhealthy, DynamoDB quickly adds a "log replica", which is a lightweight replica that only stores recent write logs. This ensures durability while a full replica is being rebuilt.
- **Smart failure detection** - Before triggering failovers, replicas check with their peers to confirm if a leader is truly unavailable, preventing disruptions from temporary network issues
- **Automatic healing** - DynamoDB's autoadmin service continuously monitors partition health and automatically replaces unhealthy replicas, ensuring your data remains triple-replicated
Interaction inside a Replication Group
DynamoDB maintains this level of availability without requiring any operational overhead from developers. You don't need to configure replication, manage failovers, or worry about cross-AZ communication - it's all handled automatically.
### 5. Fully Managed Cloud Service
DynamoDB takes another fundamentally different approach to database management compared to traditional databases - it's fully managed, meaning developers never have to worry about the underlying infrastructure. This principle goes beyond simple automation; it's baked into DynamoDB's core design:
**Resource Management**
- Developers interact purely through the DynamoDB API to create tables and perform operations
- No need to think about server provisioning, storage allocation, or cluster configuration
- The service automatically handles resource scaling based on your needs
**Operational Tasks**
- All software patching and upgrades happen transparently
- Hardware failures are automatically detected and remediated
- Backups are managed systematically without impacting performance
- Data encryption is handled automatically at rest and in transit
**Infrastructure Management**
- No need to configure distributed database clusters
- Automatic recovery from failures without manual intervention
- Built-in security features like encryption and access control
- Continuous monitoring and maintenance without downtime
The beauty of this approach is that developers can focus entirely on their application logic rather than database administration. Whether you're running a small application or handling millions of requests per second, the operational complexity remains zero.
### 6. Flexible Use Cases
While DynamoDB is often categorized as a NoSQL database, it's designed with flexibility in mind, accommodating various data models and consistency requirements. This flexibility manifests in several key ways:
**Data Model Flexibility** - DynamoDB doesn't force developers into a particular data model or consistency model. DynamoDB tables don't have a fixed schema but instead allow each data item to contain any number of attributes with varying types, including multi-valued attributes. Tables use a key-value or document data model.
**Consistency Options** - Developers can choose between eventual or strong consistency for reads, which allows applications to balance performance and consistency reads. You could choose to have strong consistency for critical operations and eventual consistency for better performance when absolute consistency isn't required.
**Query Patterns** - DynamoDB supports both single item operations and range queries, with secondary indexes for flexible access patterns and global tables for low latency multi region access. It also supports ACID transactions across items without compromising the scalability, availability, and performance characteristics of DynamoDB tables.
## Common Pitfalls
While DynamoDB's architecture solves many scaling challenges, teams often hit roadblocks when approaching it with a traditional database mindset. Here are common pitfalls to avoid:
### Poor Partition Key Design
- Using sequential IDs as partition keys, causing write hotspots
- Using too few unique partition keys, leading to throttling
- Using highly correlated values (like dates) that create temporal hotspots
- **Better Approach**: Choose partition keys with high cardinality and good distribution. Consider composite keys or adding random suffixes for better distribution
### Inefficient Access Patterns
- Creating too many indexes, increasing write costs and complexity
- Not aligning schema with query patterns
- **Better Approach**: Design your schema around your access patterns. Start with your queries and work backwards to your data model.
### Over-Relying on Secondary Indexes
- Creating an index for every possible query pattern
- Not considering the write amplification cost
- **Better Approach**: Use sparse indexes and carefully evaluate the cost-benefit of each index
### Inappropriate Item Size
- Storing items that approach the [400KB limit](https://arc.net/l/quote/axjqkgtw), not considering item size growth over time
- **Better Approach**: Consider chunking strategies for large items, and plan for data growth.
> Having faced these challenges at scale, I'll share our journey of overcoming them in an upcoming article
## Cost Optimization Strategies
One of the most painful lessons teams learn with DynamoDB is how quickly costs can spiral without proper planning. Let's dive into strategies that can help you optimize costs while maintaining performance.
### Choosing Your Capacity Mode
DynamoDB offers two capacity modes, each with its own trade-offs.
**Provisioned capacity**
Provisioned Capacity is best for predictable workloads and lowers cost when properly sized. But it requires careful capacity planning and one should also consider using auto scaling to handle traffic variations.
**On-demand capacity**
On-demand capacity is perfect for unpredictable workloads or development environments where traffic patterns are still unclear. While it might cost more than steady-state workloads, the operational simplicity and peace of mind can be worth the premium.
### Smart Capacity Planning
Success with DynamoDB requires a data-driven approach to capacity planning. Start by monitoring your CloudWatch metrics to understand your usage patterns. Look for daily and weekly trends, seasonal spikes, and any anomalies. If you're just starting out, consider using on-demand capacity during development - the usage data you gather will be invaluable for optimizing costs later.
### Lifecycle Management
Just like cleaning out your closet, regularly reviewing and managing your data can lead to significant savings. Use TTL (Time To Live) for temporary data like session information or logs. For historical data that you need to keep but don't access frequently, consider archiving to S3. Another often-overlooked strategy is using sparse indexes - they not only improve query performance but can significantly reduce storage costs.
### Stay Alert: Monitor Your Costs
The best way to avoid cost surprises is to stay vigilant. Set up CloudWatch alarms for throttling events - they're often a sign that your capacity planning needs adjustment. Monitor your consumed capacity against what you've provisioned to identify opportunities for optimization. Track costs at a granular level - by table and index - to understand where your money is going. Most importantly, set up budget alerts to catch any unexpected increases before they become painful surprises.
## Bringing It All Together
DynamoDB's architecture represents a fundamental shift in how we think about databases. Its design principles - from predictable performance to global admission control - weren't chosen arbitrarily, but evolved from real-world challenges of running databases at scale.
As I've experienced firsthand at Zomato, success with DynamoDB requires embracing these principles rather than fighting them. Whether it's rethinking our partition keys for better distribution, chunking large items for efficient storage, or carefully planning our capacity needs - each decision needs to align with DynamoDB's architectural foundations.
DynamoDB isn't just another database with a different query language. By understanding its principles and avoiding common pitfalls, you can harness this same power for your applications, regardless of scale. The effort you invest in understanding its architecture and aligning your design decisions with its principles will pay dividends in scalability, reliability, and operational simplicity.
### References
- [Amazon DynamoDB: A Scalable, Predictably Performant, and Fully Managed NoSQL Database Service (USENIX ATC '22)](https://www.usenix.org/system/files/atc22-elhemali.pdf)
- [Insights from Paper: Amazon DynamoDB](https://hemantkgupta.medium.com/insights-from-paper-part-i-amazon-dynamodb-a-scalable-predictably-performant-and-fully-6d93dfbfe2fb)
---